Generative AI on AWS
Run Amazon Bedrock securely inside your own AWS account
We set up foundation models to work directly on your business documents and applications, using your existing identity system and network boundaries.
Secure model setup
Foundation models working inside your own network boundaries
Amazon Bedrock runs over your existing AWS footprint, bringing large language models to your documents. Requests stay entirely inside your account boundary, relying on your current identity system and leaving a clear log of activity.
- 1
Private network path
VPC endpoints provide private connectivity, ensuring your API calls to models never cross public internet lines.
- 2
Scoped access roles
IAM roles are strictly limited to exactly what each application calls, avoiding long-lived credentials in environment files.
- 3
Strict content boundary
Documents stay safely in your storage, and all inference requests remain fully contained inside your own AWS account boundary.
Amazon Bedrock configured for your kind of business
Amazon Bedrock suits organizations already running on AWS, leveraging your existing network and permissions model. We configure guardrails and scope IAM roles strictly to what each application calls.
Select your industry
Review related service pages
Console views of your model environment
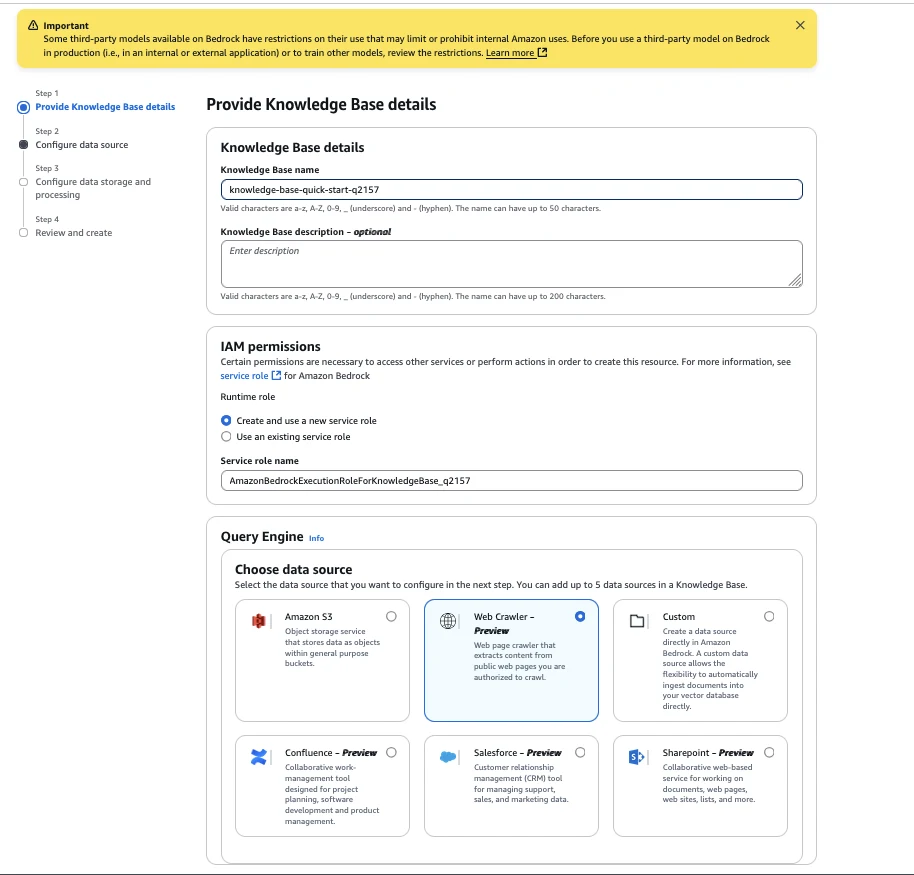
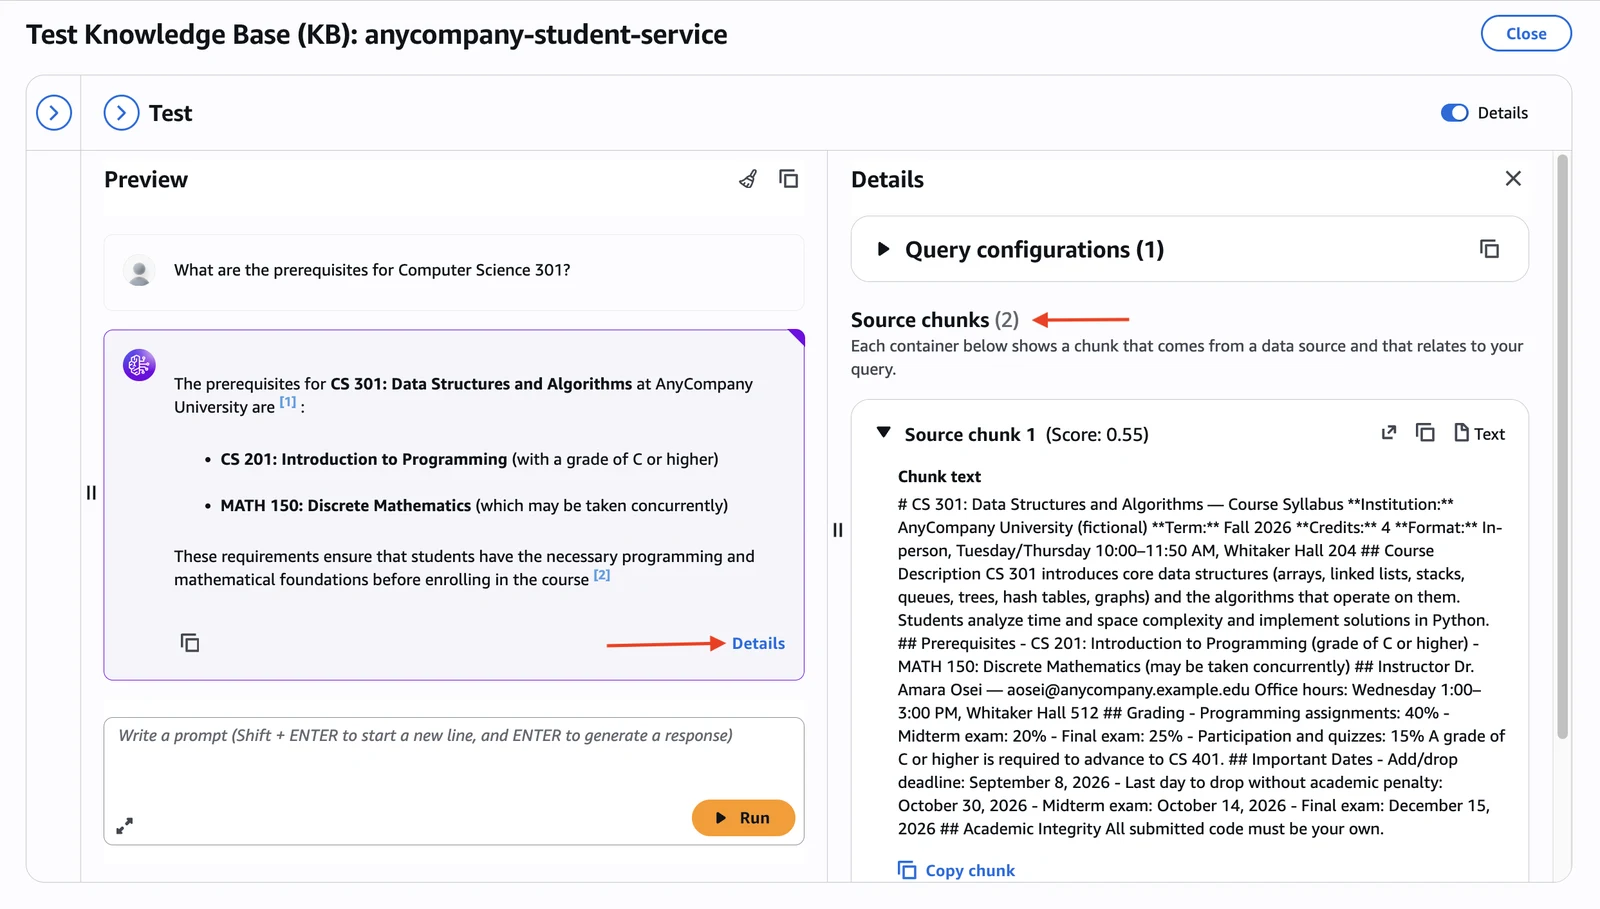
AWS provides strong controls for connecting data and limiting responses. We configure native tools to manage your documents, cite sources, mask sensitive data and track your spend.
Select a console view
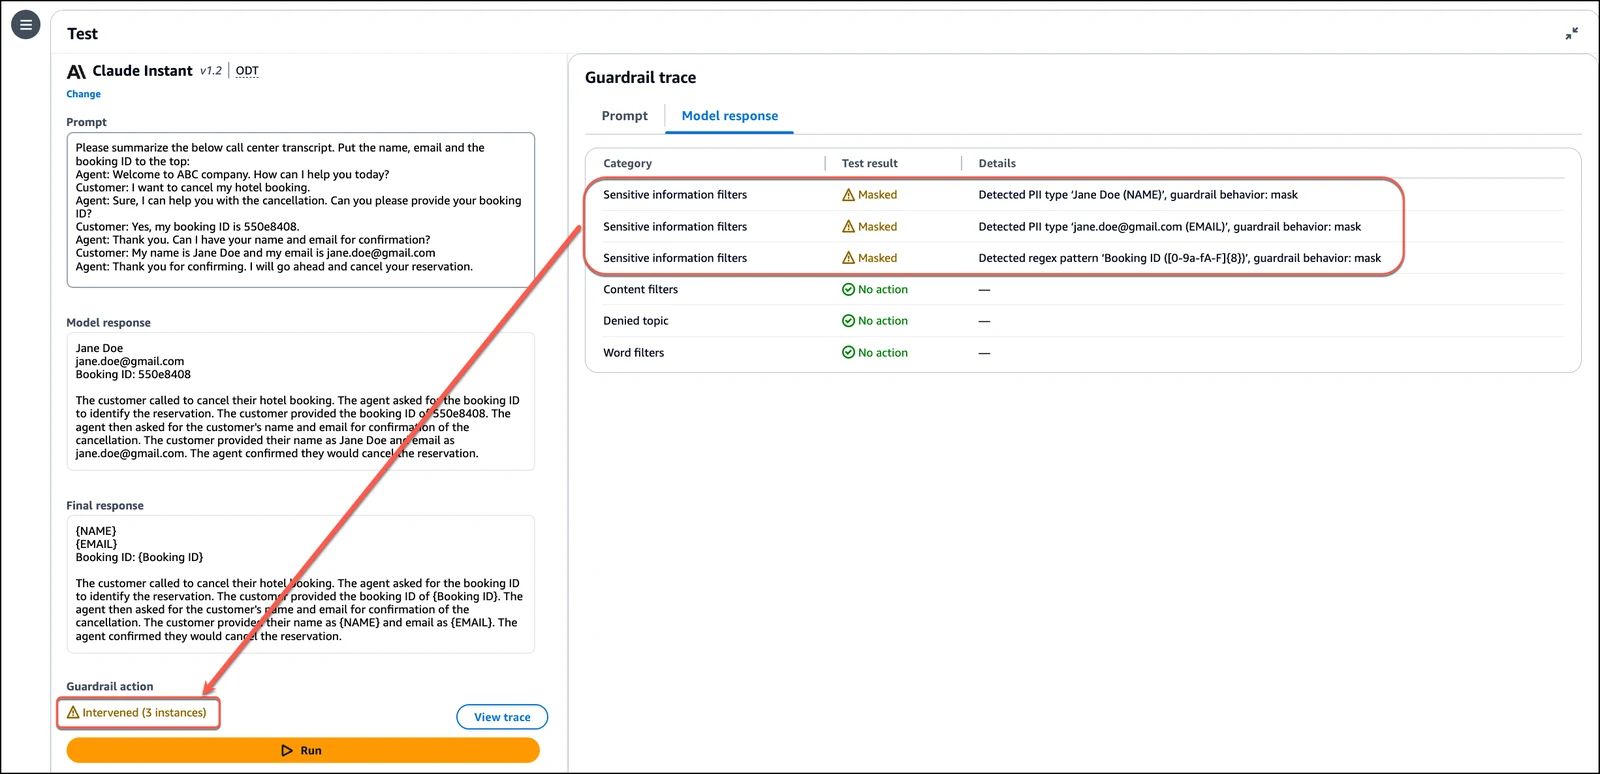
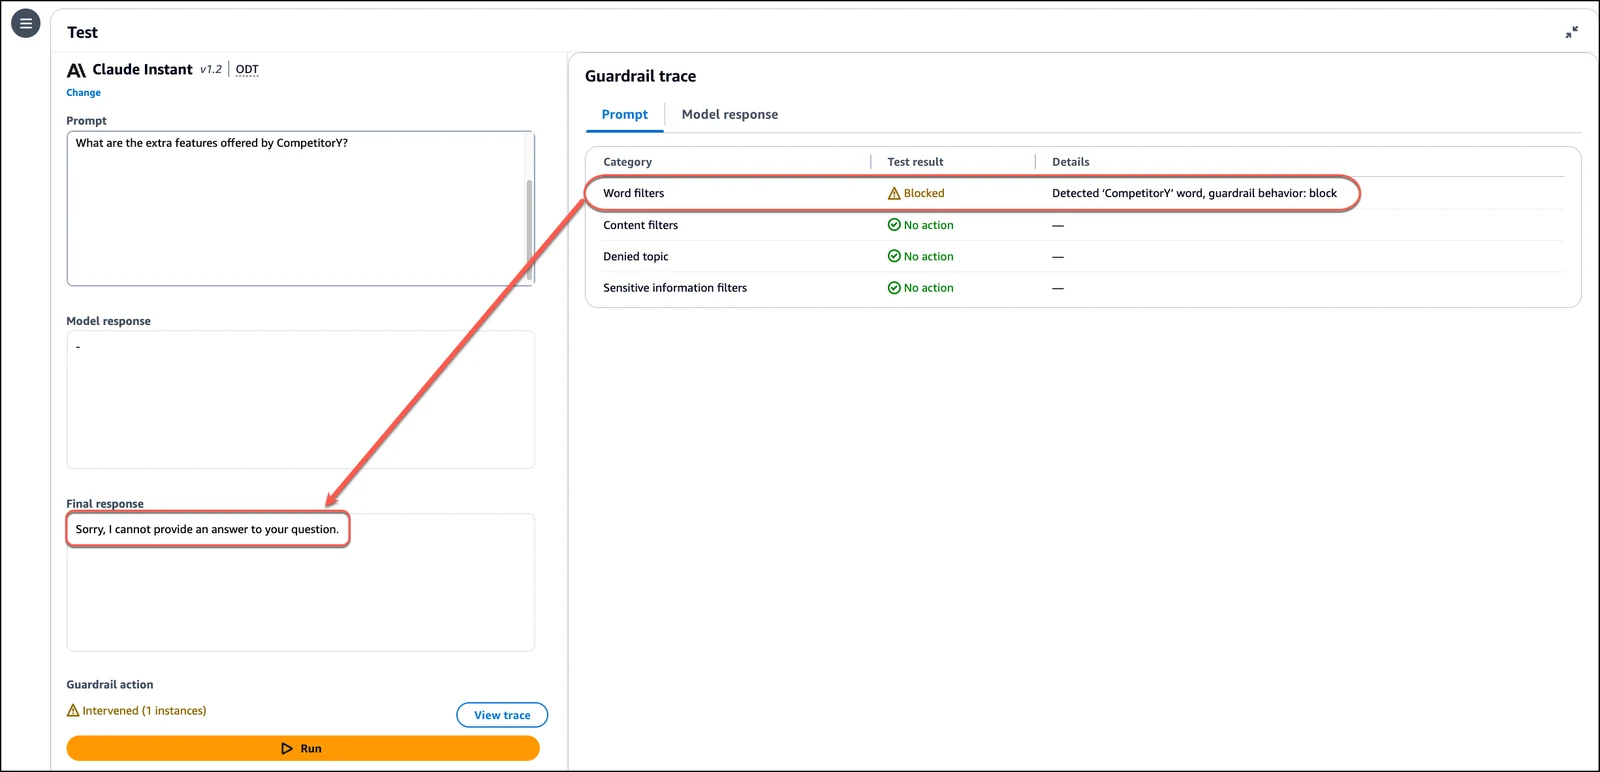
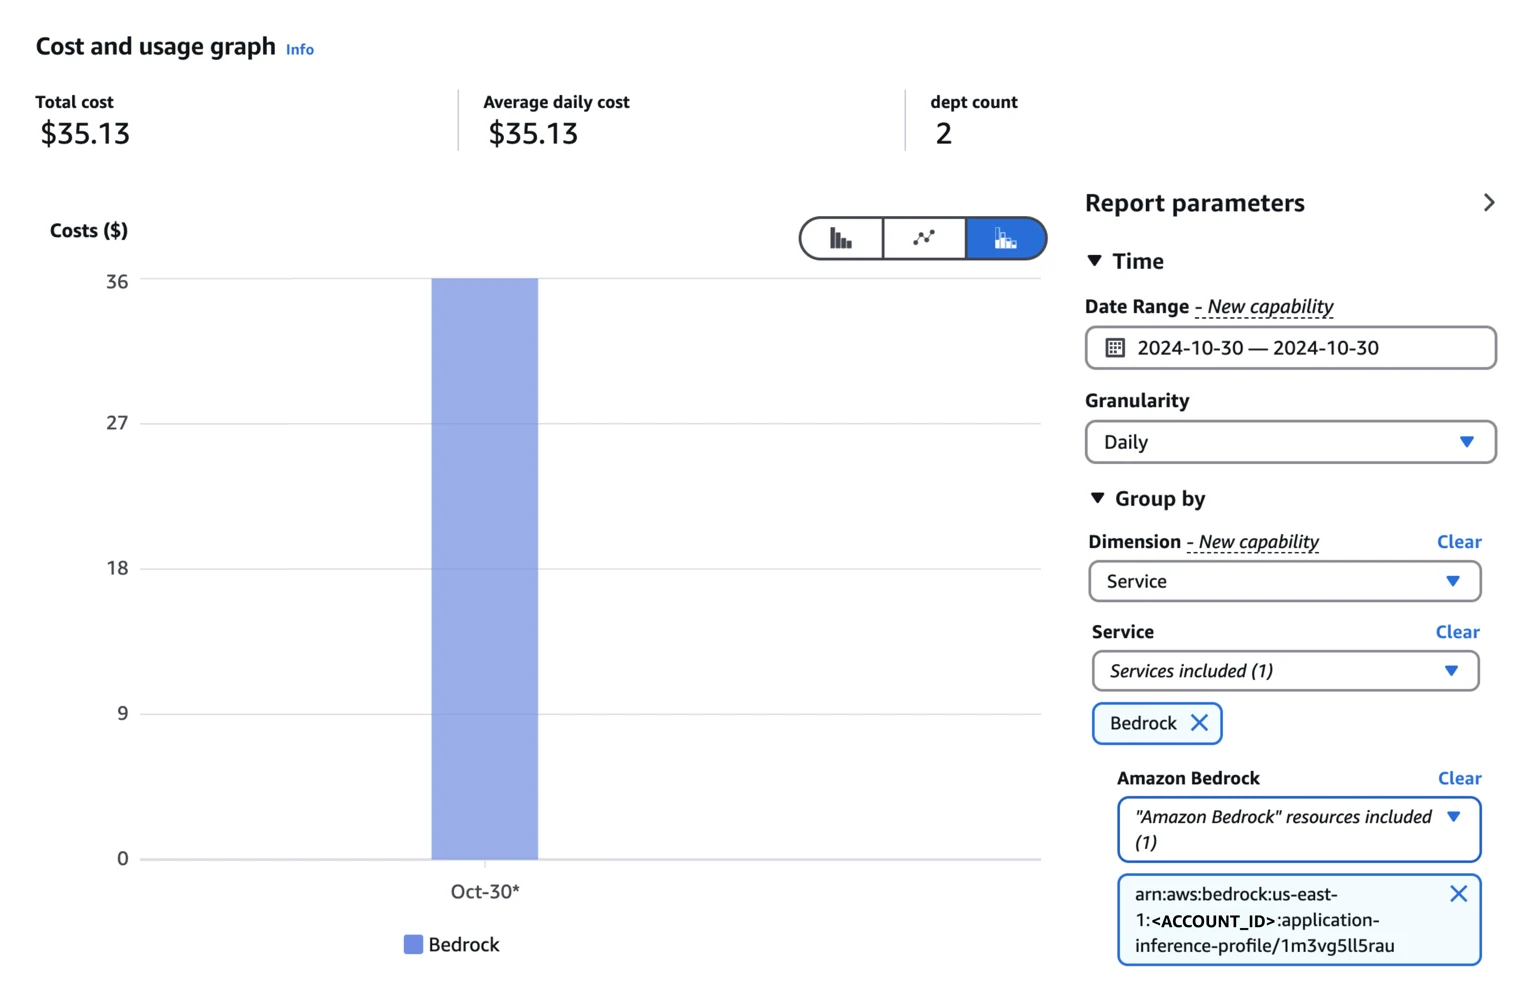
Typical configurations built for local businesses
Typical configurations include retrieval over S3 buckets, models added directly to existing applications, automated document extraction inside current pipelines, and governed internal endpoints.
Choose a build type
Sample request
Checks performed before project handover
Deployments finish after checking model and region availability, matching throughput to your request pattern, testing filters on realistic inputs, and running any replacement on the same evaluation set.
Model and region availability
Model choice and region are set against availability, since not every foundation model is enabled in every region or across every AWS account.
Throughput matching
On-demand and provisioned throughput behave differently under load. Configurations match exactly to your expected request pattern to manage costs.
Input and output filtering
Filters for what the workload should refuse are thoroughly tested against realistic inputs, confirming your guardrails catch denied topics.
Replacement model evaluation
Superseded models require careful transitions. Replacements run against the same evaluation set before switching, validating performance despite non-deterministic outputs.
Setting up models in your environment
Work often happens alongside the in-house team that owns the AWS account. Getting IAM role boundaries right takes much longer than simply wiring the model calls.
- 1
Review account structure
We inspect your existing AWS footprint, examining network boundaries, identity systems and regional availability to plan deployments.
- 2
Enable and fence model access
We configure your service control policy around Bedrock and deploy VPC interface endpoints so calls avoid public networks.
- 3
Connect content securely
We link models directly to your data sources, keeping permissions checked first so queries only reach approved S3 buckets.
- 4
Hand over with clear tracking
We hand over a finished build complete with thorough logging and cost allocation tags tracing spend to specific workloads.
Common questions from operations leads
- Where does our content stay?
Content stays entirely in your own storage, and all model requests stay strictly inside your AWS account boundary.
- Which models can we use?
Amazon Bedrock offers managed access to models from Anthropic, Meta, Mistral and Amazon through one API. Availability depends on your specific AWS account and region settings.
- How is spend tracked?
Spend tracks tokens and requests rather than user seats. Cost Explorer filters down to application inference profiles, so exact costs trace back to the specific workload that caused them.
- What is the difference between on-demand and provisioned throughput?
On-demand and provisioned throughput behave differently under load and must match the request pattern. Provisioned throughput is bought at a fixed hourly cost in model units, which a customized model must use.
- We use Microsoft 365 for staff and AWS for our product, which do you set up?
Microsoft 365 businesses are typically directed to Microsoft Foundry, while AWS-native workloads use Bedrock. Some clients run both, and our work spans both platforms to match your architecture.
- What happens when a model is retired or replaced?
Testing new models against your specific inputs is crucial. Replacements run against the same evaluation set before switching, proving they handle your tasks properly before going live.
Start building securely in your account
Book a conversation to discuss your AWS environment and test foundation models on your own documents.